A no-code web scraper that collects website data on a schedule.
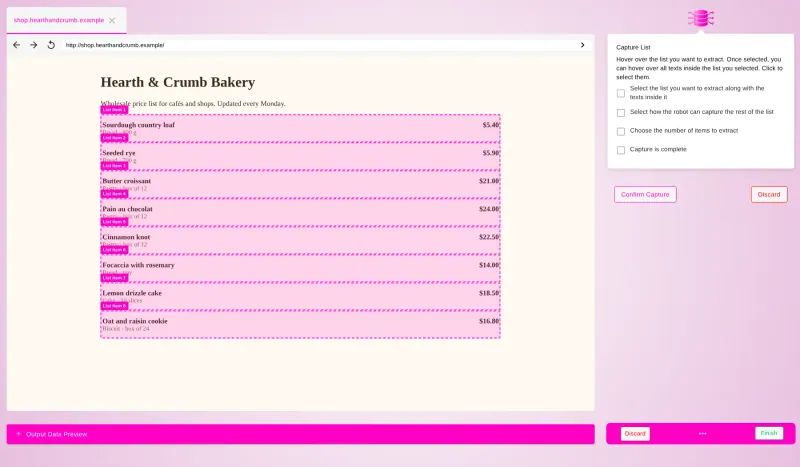
Works the way Browse AI does: open a website in its recorder, click the list or text you want, and save it as a robot that runs on demand, on a schedule or through an API, with results as CSV, JSON or Markdown or sent to a webhook. It has no credits, but it is early software (version 0.1.0) with no ready-made robots, and anti-bot protection, CAPTCHA bypass, proxy rotation, email alerts and teams are only in its paid Maxun Cloud.
What you gain
- No credits or page limits, only the cost of your server
- The data you collect stays on your own server
- Robots, schedules and the API are included free
What is different
- No built-in anti-bot protection, CAPTCHA solving or rotating proxies, so heavily protected sites may block it (you can add your own proxy)
- No ready-made robots for popular sites; you train each one yourself
- No email alerts or shared team workspaces, which are part of the paid Maxun Cloud