S

Open-source alternative to ScrapingBee

Crawl4AI is a free, open-source ScrapingBee alternative that loads web pages in a real browser on your own server and returns them as clean Markdown, JSON, screenshots or PDFs. ScrapingBee sells monthly credit plans and cannot be self-hosted; Crawl4AI has no per-request fee, though it has no rotating proxies, so sites with strong bot protection may block it.

Free app Code: Open source Import from ScrapingBee: No Some setup

Why look for an alternative to ScrapingBee?

ScrapingBee is a hosted web-scraping API: you send it a link and it fetches the page with headless browsers and rotating proxies, then returns the page or the data you asked for. It is sold as monthly plans of credits and cannot be self-hosted.

Developers look for an alternative because credits run out as volume grows, and some would rather fetch pages from their own server. Crawl4AI does the fetching and rendering on your server with no per-request fee; you bring your own proxies for sites that block it.

How Crawl4AI compares

Turn any web page into clean Markdown or data for your AI tools.

Does ScrapingBee's fetch-and-render job on your own server, loading each page in a real Chromium browser with no per-request fee, and adds clean Markdown output and AI extraction. ScrapingBee's rotating proxies and bot-protection handling are not included: requests come from your server's address, and you add proxies of your own when you need them.
Some setup Open source

Moving from ScrapingBee

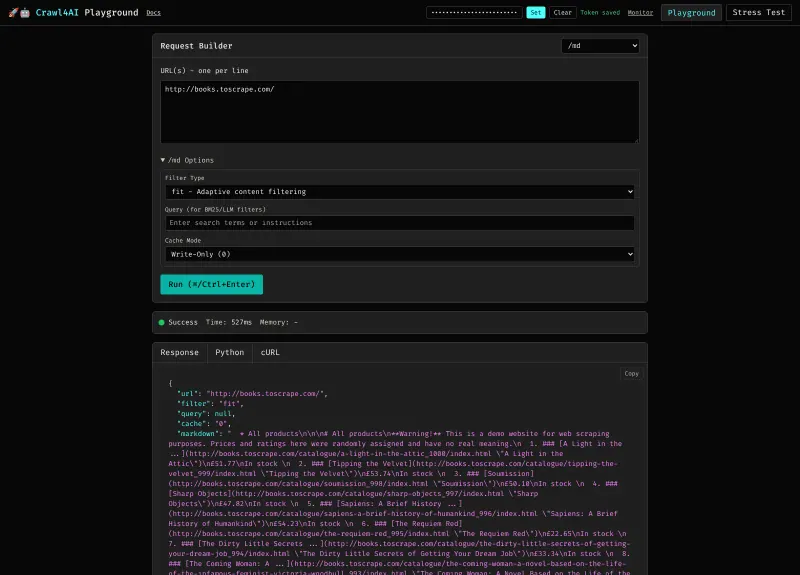
There is nothing to import: ScrapingBee is an API, so you rewrite your requests for Crawl4AI's endpoints. Build each request in Crawl4AI's playground, copy the Python or cURL version into your code, and send Crawl4AI's API token with it. Test the sites you scrape most first, since requests now come from your server's address without ScrapingBee's proxies, and keep a small ScrapingBee plan only for sites that block your server.

Questions

What is the best open-source alternative to ScrapingBee?

Crawl4AI is the free, open-source alternative to ScrapingBee for fetching web pages through an API in the catalogue today. Does ScrapingBee's fetch-and-render job on your own server, loading each page in a real Chromium browser with no per-request fee, and adds clean Markdown output and AI extraction. ScrapingBee's rotating proxies and bot-protection handling are not included: requests come from your server's address, and you add proxies of your own when you need them.

Does Crawl4AI include proxies like ScrapingBee?

No. Self-hosted Crawl4AI has no proxy network, so requests come from your server's address and some sites block or challenge them. You can add proxies of your own.

Is there a request limit in Crawl4AI?

No. Unlike ScrapingBee's monthly credits, Crawl4AI has no per-request fee or quota; how much it fetches depends on your server, which needs at least 4 GB of memory because each page loads in a real browser.

Can I self-host ScrapingBee?

No. ScrapingBee is a hosted API only, sold as monthly plans of credits. Crawl4AI is a self-hosted option: it fetches and renders pages in a real Chromium browser on your own server and returns clean Markdown.

Is Crawl4AI really free compared with ScrapingBee?

Yes, Crawl4AI is free. To run them you need Cloudgate and a server. Use hosted Cloudgate, which can also provide the server, or install Cloudgate on a server of your own for free. Cloudgate's plans and prices are at cloudgate.octabyte.io/pricing. One server can run several apps.

Do I need a developer to replace ScrapingBee?

Yes. Crawl4AI is used through its API, its Python library or an AI assistant, so someone needs to connect it to your code or workflow tool. Cloudgate installs it, gives it a secure web address and creates its API token, and the playground in the browser helps you build the requests.