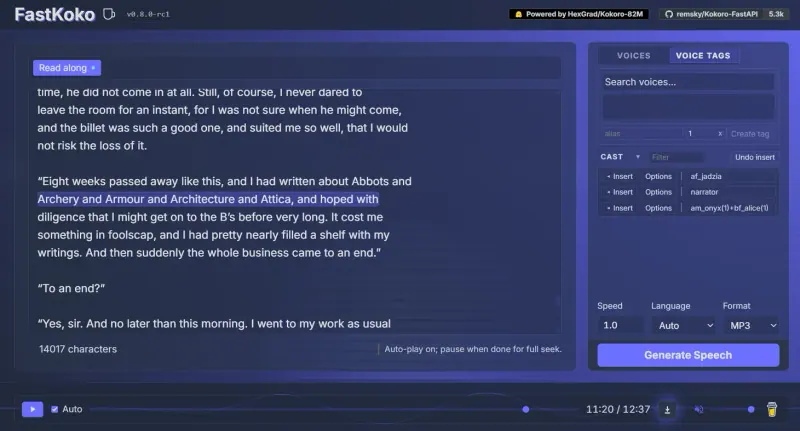
Text to speech with natural voices, no GPU needed.
Offers the same /v1/audio/speech API as OpenAI, with streaming, and maps OpenAI's voice names such as alloy to its own voices, so most code only needs a new base address. It returns MP3, Opus, AAC, FLAC, WAV or PCM, adds word timestamps for captions, and runs on a server with no graphics card. It ignores the style instructions OpenAI's newer speech models accept, and has fewer languages.